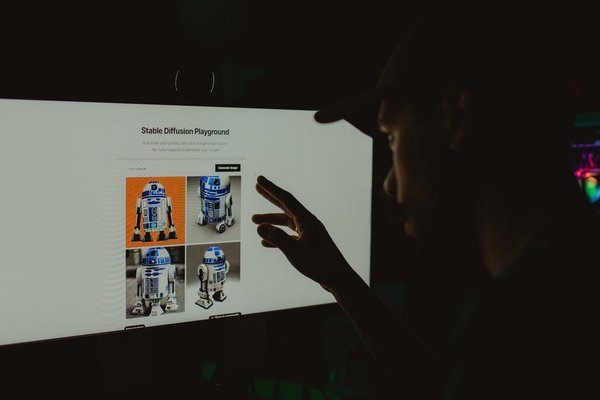
Type “a red fox reading a newspaper on a rainy train” into an AI image generator, and a scene may appear seconds later. No camera captured it, and an illustrator did not draw it in real time. The software created a new arrangement of visual details based on patterns learned during training.
So how do AI image generators work? They translate your instructions into numerical representations, then use a trained model to construct an image consistent with those instructions. The interesting part is how the model learns what a fox, newspaper, rain and train should look like together.
First, the model learns relationships between words and images
Before an image generator accepts a prompt, it undergoes training on large collections of visual material. Depending on the system, this may include images paired with captions or other descriptive information. During training, mathematical adjustments help the model learn connections between visual structures and language.
It can learn that “striped” often describes alternating bands, that “side lighting” produces characteristic shadows, and that a bicycle has parts arranged in particular relationships. It does not need a separate hand-written rule for every object.
This learning is statistical, not human understanding. Different systems also use different training datasets and filtering practices.
Diffusion models: turning noise into an image
One influential approach to AI image generation uses diffusion models. Imagine a photograph gradually covered with random static until its original subject becomes unrecognisable. During training, the model learns to predict how to reverse parts of that corruption.
When generating an image, a diffusion system can begin with random noise and refine it through a sequence of steps. At each stage, the model estimates changes that should make the result more like a plausible image matching the prompt. Shapes emerge in a broad sense; textures and details become more coherent as refinement continues.
Some diffusion systems work directly with image pixels. Others operate in a smaller mathematical representation called latent space, which can make generation more efficient. A decoder then translates that representation into the visible picture. This is why “removing noise” is a useful explanation, even though the calculations are more complicated than applying a photo-editing filter.
The image is not normally assembled by cutting matching objects out of a database. The model synthesises visual content from learned patterns, although training examples can still influence the result and sometimes lead to memorisation.
How a text prompt steers the picture
Text-to-image AI needs a way to connect language to visual generation. A text encoder or another language-processing component turns the prompt into representations the image model can use. During generation, these representations help guide decisions about subjects, their relationships and visual style.
Consider the difference between “a glass on a table” and “a glass behind a blue vase on a wooden table.” The second prompt adds information about placement, colour and materials. A capable system may follow these relationships, but complicated instructions can still be misunderstood.
Words describing lighting, viewpoint and medium also matter. “Overcast daylight,” “viewed from above” and “watercolour illustration” point toward different visual patterns. Prompt interpretation varies by model: some handle conversational requests well, while others respond more predictably to compact descriptions.
Not every image generator follows the same recipe
Diffusion is a major technique, not a universal definition of generative images. Some systems use autoregressive methods that predict sequences of visual tokens, while others combine language models, image representations and different generation strategies. Two products may offer the same text box while using substantially different machinery behind it.
A practical example: improving one prompt
Suppose you need an illustration of a robot tending a vegetable garden. Start with “a robot in a garden.” The model might produce a dramatic science-fiction scene because “robot” commonly appears beside futuristic imagery in visual training material.
Now try: “A small friendly gardening robot watering lettuce seedlings in a modest backyard vegetable bed, soft morning light, eye-level view, natural colours, no people.” This gives the system useful constraints: scale, activity, setting, light and composition.
If the robot still appears enormous, change one detail at a time: “the robot is knee-high beside the lettuce.” Keep the rest of the prompt stable so you can see which adjustment helps. When the tool offers a fixed random seed, reusing it may make comparisons more consistent, although results still depend on model settings.
Learning prompt writing techniques is useful, but endlessly adding adjectives is not. Clear relationships often improve an image more than a long list of stylistic buzzwords.
How AI image editing works
Many generative AI tools accept an existing picture alongside instructions. Instead of constructing every element from scratch, the system can use the uploaded image as a visual reference or starting point. Some tools let you select a region and describe what should change, a process often called inpainting.
For example, you might ask to replace a cloudy sky while preserving the buildings below. Other tools extend the canvas beyond its original edges, known as outpainting. The degree to which unchanged areas stay intact depends on the model, editing method and settings.
Why convincing images still make mistakes
A polished result is not proof that a model has understood every detail. Hands, reflections, object counts, labels and spatial relationships can fail because the system predicts a plausible visual arrangement rather than verifying the scene against physical reality.
Newer models may spell words more accurately, yet small typography and precise layouts can remain unreliable. A generated medical diagram or historical reconstruction can look authoritative while including invented details. Check images carefully when accuracy matters.
There are questions beyond visual quality. A convincing image can mislead viewers about real events. Training-data provenance, consent, intellectual property and commercial-use rules vary by provider and jurisdiction. Avoid entering private material into a service before reviewing its policies, and distinguish fictional illustrations from documentary evidence.
Frequently asked questions
Do AI image generators search the internet for a matching photo?
Most do not simply retrieve a ready-made picture when you submit a prompt. They generate an output using a trained model. Some products add retrieval or reference-image features, so the workflow depends on the service.
Why does the same prompt produce different images?
Many generation methods include randomness, often introduced through an initial seed. Changing the seed, settings or model version can produce a different composition even when your words remain the same.
Can an AI image generator copy an existing artist’s work?
Models can reproduce learned stylistic characteristics and may occasionally produce content resembling specific training examples. Similarity, copyright questions and permitted uses require case-by-case consideration rather than assuming every output is original or infringing.
Does a longer prompt always improve the image?
No. A longer prompt can introduce contradictions or competing details. Start with the subject, action and setting, then add only the visual constraints that matter most.
The simple idea to remember
An AI image generator learns associations between visual patterns and instructions, then uses those associations to create an image. Diffusion models often do this by progressively refining noise, while other architectures take different routes. Once you understand that the software generates a plausible interpretation—not a photograph of reality—you can write better prompts, edit with purpose and judge the finished image more critically.